 Crypto.
 About
 Passport
 Conference call
 send money
 Voorwaarden
 Privacy
 Sierra market
When AWS Operations Become a Business Bottleneck: The Case for Managed Cloud Services
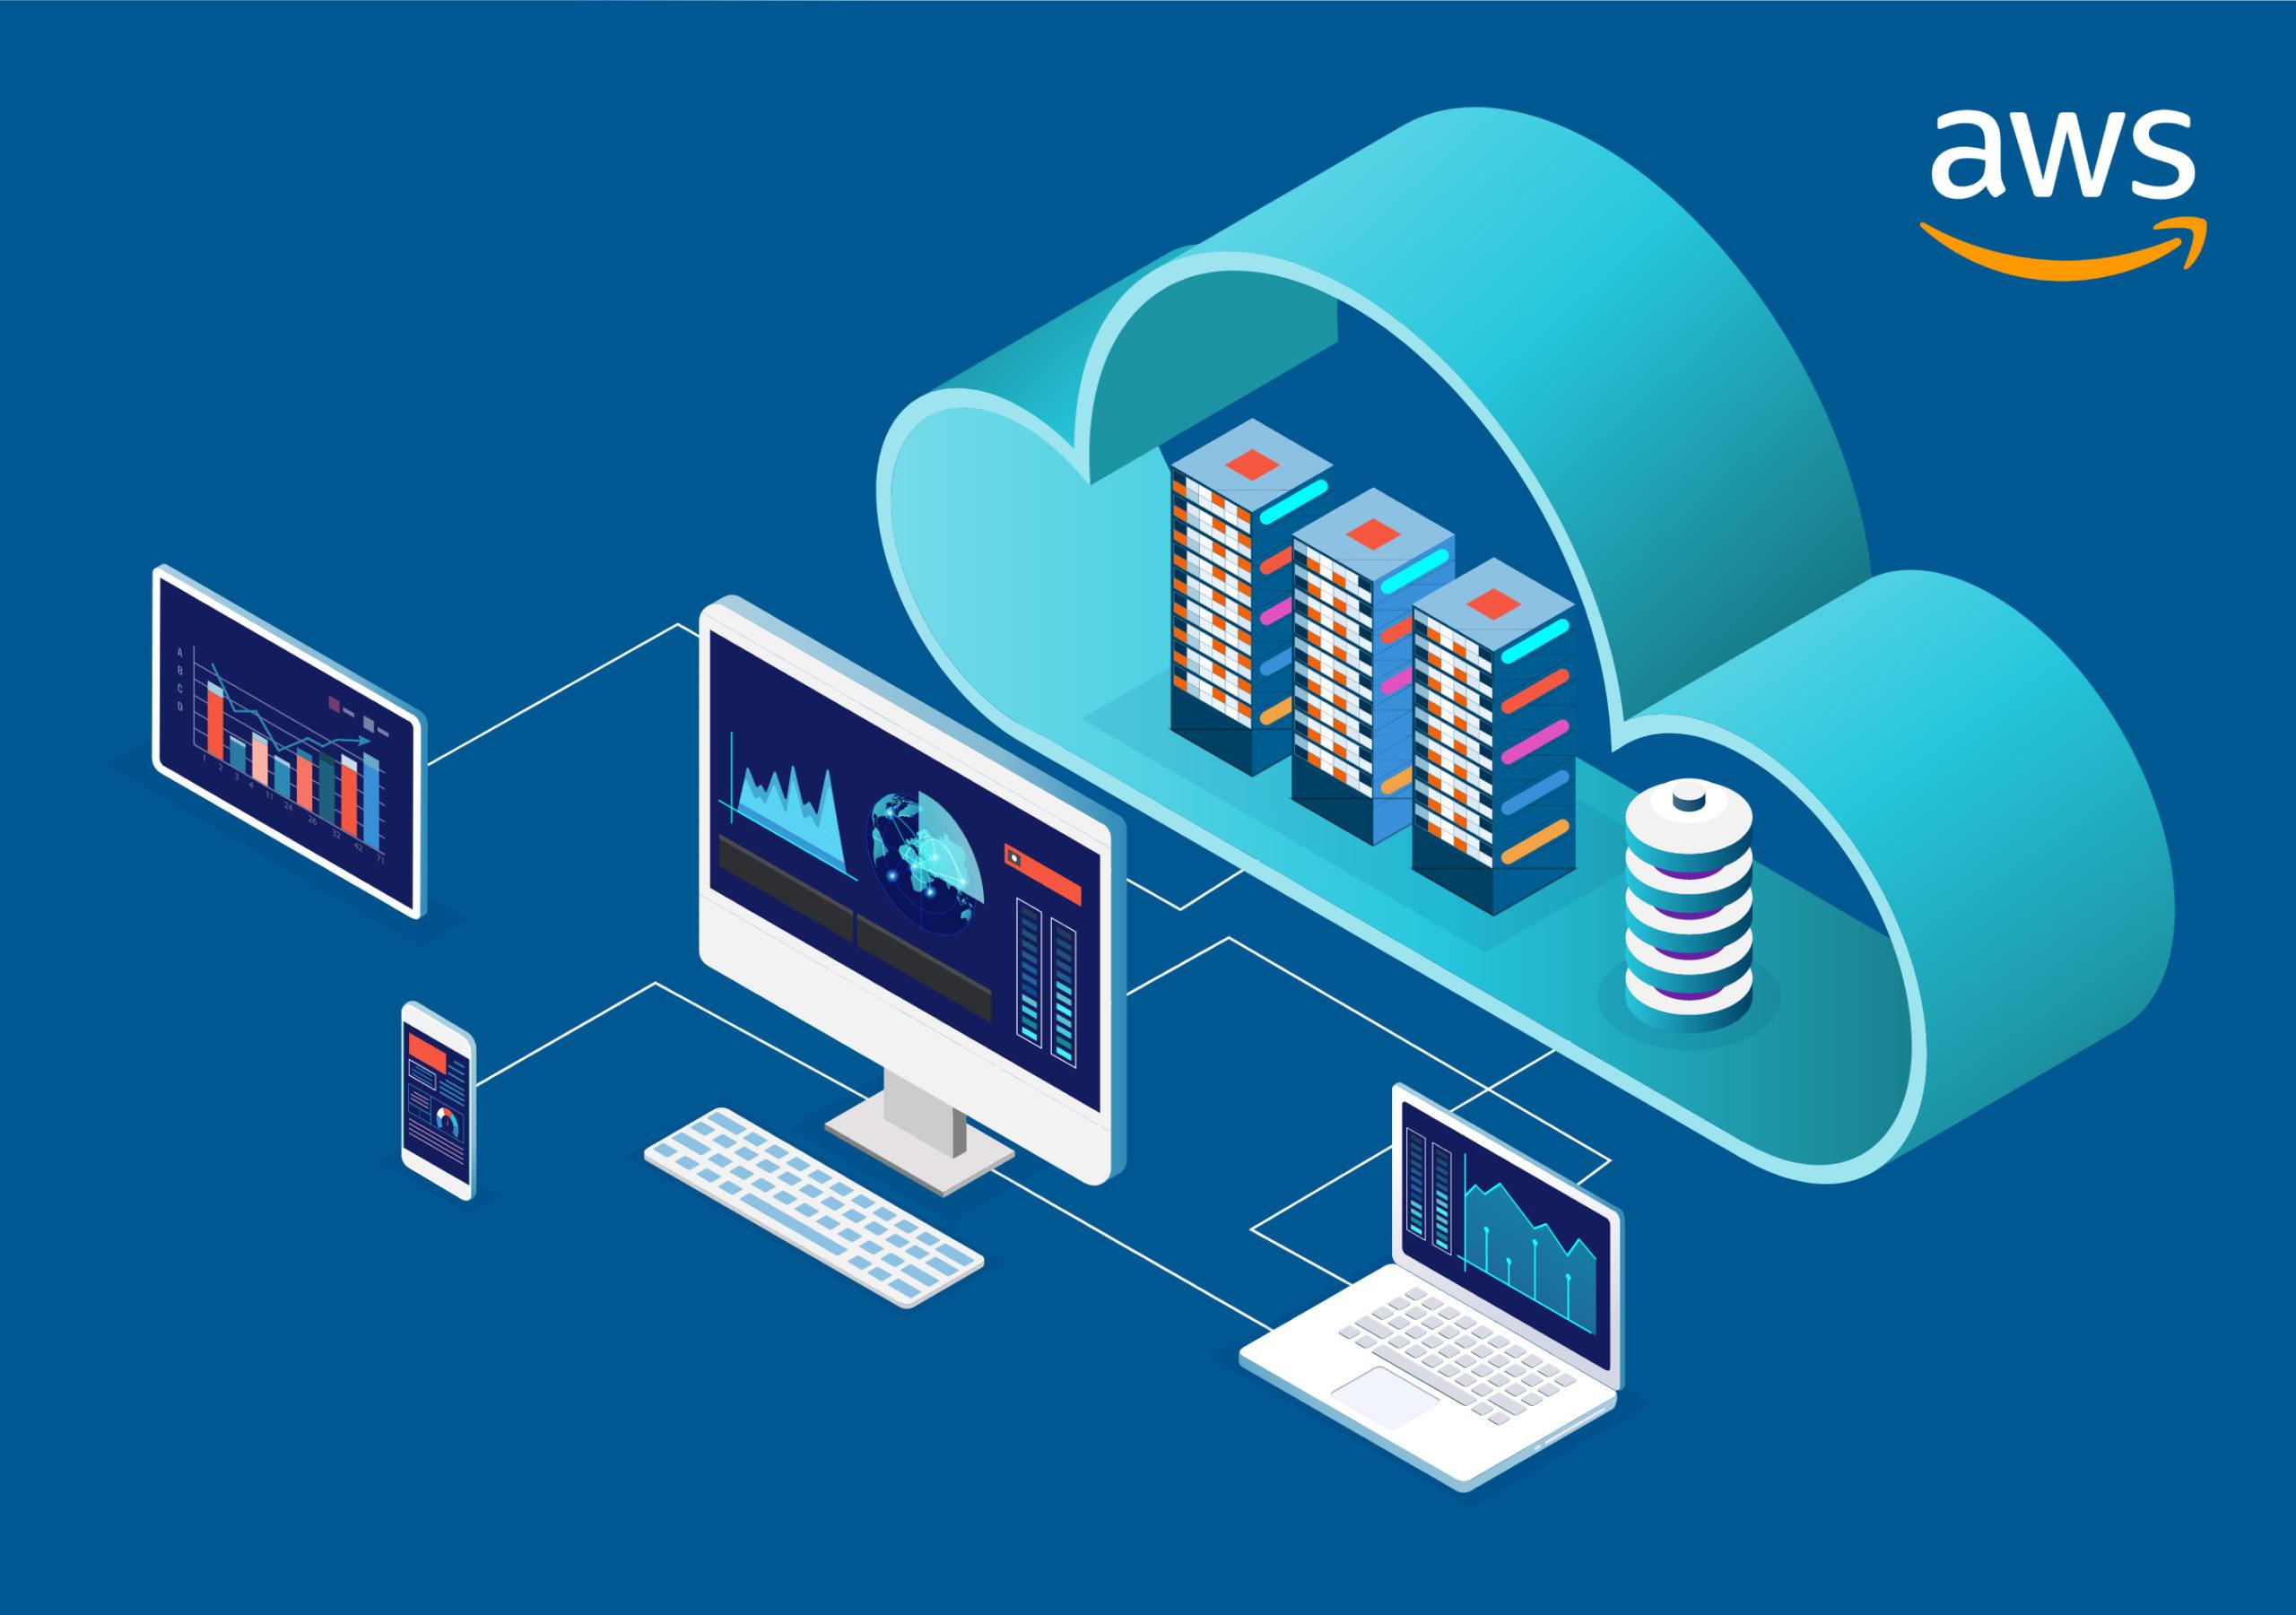
An AWS environment can become expensive and difficult to manage long before anyone realizes there is a problem. A few oversized EC2 instances may go unnoticed. Storage resources can accumulate, backups may be created without being tested, and security configurations can slowly drift away from best practices. At the same time, internal developers are often expected to monitor infrastructure, respond to incidents, manage databases, and keep applications running while still delivering new product features.
This is where managed cloud services aws solutions can make a practical difference. Instead of asking an already busy internal team to own every operational responsibility, businesses can bring in specialized expertise to monitor, maintain, secure, and optimize their AWS environments. The goal is not simply to outsource technical tasks. It is to create a more predictable cloud operation that supports growth without allowing infrastructure management to become a permanent distraction.
Why AWS Management Becomes Complicated
AWS provides a vast collection of services, but flexibility also creates responsibility. Organizations using EC2, RDS, Aurora, EKS, ECS, Auto Scaling, CloudWatch, and other services need people who understand how these components behave individually and as part of a larger architecture.
That responsibility grows as workloads become more important.
A SaaS company may require continuous availability because customers depend on its platform throughout the day. An ecommerce company may experience dramatic traffic changes during promotions. A financial technology business may need stronger access controls and detailed governance because of the sensitivity of its data.
In each case, infrastructure that was manageable at a smaller scale can become increasingly difficult to operate manually.
The challenge is often not a lack of technical ability. It is a lack of available time. Engineers who should be working on application development can find themselves investigating alerts, reviewing IAM permissions, troubleshooting database performance, or responding to overnight incidents.
Turning Reactive Support Into Proactive Operations
One of the most important differences between basic cloud support and genuine operational management is timing.
Reactive support begins after something goes wrong. Proactive management attempts to identify warning signs before they become business-impacting incidents.
A structured AWS managed services approach can include continuous monitoring of infrastructure, applications, databases, and security events. CloudWatch metrics and logs can help teams identify unusual resource behavior, while Grafana and other observability tools can provide broader visibility into application performance.
This matters because a small performance problem is often easier to solve than a full outage.
For example, an instance showing sustained resource pressure can potentially be resized or redistributed before customers experience degraded performance. Database trends can reveal capacity issues before they affect transactions. Automated alerts can ensure that important events reach the appropriate technical team without depending on someone manually checking dashboards.
The objective is simple: identify operational problems while they are still manageable.
Controlling AWS Costs Before the Invoice Becomes a Surprise
Cloud costs rarely become excessive because of one dramatic mistake. More often, unnecessary spending develops gradually.
Unused resources remain active. Instances are larger than workloads require. Snapshots accumulate. Development environments operate outside working hours. Purchasing decisions are made without reviewing actual usage patterns.
This makes ongoing optimization more valuable than a one-time cost audit.
An experienced AWS managed services provider can regularly review resource utilization and use tools such as AWS Cost Explorer and Compute Optimizer to identify opportunities for improvement. EC2 rightsizing, storage cleanup, scaling adjustments, and appropriate Reserved Instance or Savings Plans strategies can all contribute to more efficient spending when applied according to actual workload requirements.
The benefit is not simply a lower monthly invoice. Predictable cloud economics make budgeting easier and allow businesses to understand where their infrastructure investment is actually going.
Security Requires Continuous Attention
Cloud security cannot be treated as a configuration that gets completed once and then forgotten.
Users change roles. Applications evolve. New resources are deployed. Permissions expand. Software requires patching. As environments grow, small configuration changes can create security gaps if they are not reviewed regularly.
Managed AWS cloud support can incorporate ongoing IAM governance, access reviews, security monitoring, WAF configuration, and threat detection. Services such as GuardDuty can contribute to identifying suspicious activity, while AWS security controls can be incorporated into a broader operational framework.
Regular reviews also create an opportunity to identify excessive permissions and outdated configurations before they become larger problems.
For businesses operating in regulated environments, governance becomes even more significant. Documentation, reporting, access controls, and defined operational responsibilities can support compliance efforts while providing clearer accountability.
Supporting Databases and Applications at Scale
AWS infrastructure is more than virtual machines.
Amazon RDS and Aurora databases require monitoring, performance analysis, capacity planning, backups, and configuration management. If database resources are not maintained appropriately, application performance can suffer even when the underlying EC2 infrastructure appears healthy.
Similarly, Auto Scaling configurations need to reflect real workload behavior rather than remaining permanently tied to their original assumptions.
Managed cloud services can help organizations continuously evaluate these components. Scaling thresholds can be adjusted based on observed usage, database performance can be monitored, and capacity decisions can be made before limitations become customer-facing problems.
For containerized applications, the operational requirements can become even broader. EKS and ECS environments require ongoing attention to clusters, deployments, networking, scaling, and configuration consistency. Without active management, configuration drift can accumulate quietly over time.
Backups Are Only Valuable When Recovery Works
A backup strategy can look excellent on paper and still fail when an organization actually needs it.
Scheduling AWS Backup jobs and creating EBS snapshots are important steps, but they do not automatically prove that recovery will work under pressure. Backup validation and recovery testing are therefore critical parts of responsible cloud operations.
Managed services can establish recurring processes for checking backup status, reviewing retention policies, and testing recovery procedures. This turns disaster recovery from an assumption into a process that can be measured and improved.
For businesses where downtime can directly affect revenue or customer trust, that distinction is particularly important.
Giving Internal Teams Their Time Back
Perhaps the greatest benefit of managed cloud services aws engagements is not technical at all.
It is time.
When an external team takes responsibility for routine monitoring, infrastructure maintenance, cost reviews, security governance, and incident response, internal engineers can spend more time building products and improving customer experiences.
That does not mean the internal team loses control. Instead, responsibilities can become clearer. Internal engineers can focus on architecture and development while managed-service specialists handle defined operational responsibilities according to agreed processes and service levels.
This division can become especially valuable as a company grows. Hiring enough internal specialists to cover every AWS operational discipline may not always be practical, while ignoring those disciplines creates its own risks.
What Effective AWS Managed Services Should Deliver
A successful engagement should ultimately be measurable.
Businesses should be able to evaluate whether AWS waste is decreasing, incidents are being addressed more efficiently, security processes are becoming more consistent, and internal engineering capacity is being recovered.
The strongest arrangements combine monitoring, optimization, security, governance, backup management, and technical support rather than treating each issue as an isolated ticket.
Infrastructure-as-code tools such as Terraform or CloudFormation can further improve consistency by making environments reproducible and auditable. Defined reporting and regular operational reviews can then provide visibility into what has changed, what needs attention, and where future improvements may be possible.
Looking Beyond AWS Management
AWS infrastructure will continue to evolve, and businesses will continue to demand greater performance, security, scalability, and cost efficiency from their cloud environments. The question is increasingly less about whether an organization can run AWS and more about whether it can operate AWS efficiently while continuing to move the business forward.
That is the central value of managed cloud services aws solutions: creating operational ownership that keeps infrastructure healthy without consuming the attention of the people responsible for building the future.
As cloud environments become more interconnected and business-critical, organizations should consider an important question: how much of their engineering capacity should be spent maintaining infrastructure, and how much could be redirected toward innovation if operational responsibility were managed more systematically?
Bub
Do?

Categorieën
Read More
Proton VPN Enhances Linux App with Beta Split Tunneling Functionality Linux users of Proton VPN can now access the split tunneling feature in beta, marking a significant upgrade to the platform's capabilities on this operating system. The new functionality allows subscribers to choose which applications or IP addresses route through the VPN connection, while allowing other traffic to bypass...
The Evolution system returns to EA SPORTS FC 26 with more depth and strategic importance than ever. Because the game’s power curve progresses more slowly this year, special cards are rarer, making every upgrade you choose count. You’ll find two main Evolution categories: Training Camp Evolutions, which require no in-game objectives and can be completed through the web or companion...
Lorsque le lunigecko active son pouvoir, une structure minérale émerge du sol pour le protéger. Sa défense se compose de multiples barrières, qu'il faut briser une à une avec une grande précision. Les techniques les plus efficaces combinent la force de l'élément Géo et la puissance cristalline. Une fois son bouclier final...
Running payroll can look simple when a business has only a few employees. In reality, every payday connects wages, tax, National Insurance, pensions, statutory payments, employee records, and HMRC reporting. A missed detail can quickly become a correction exercise, while a smooth payroll process can make the business feel more organised and trustworthy. For owners learning how to Manage...
Elegance Types The Row Bags Sale Online At Tldbbags.com